Research Notes
AI tools, certifications, books and small experiments, written down while learning. 73 posts.
Gooaye EP709, 28 Oct 2026: I Thought Models Would Be Commoditised Into Utilities — This Filing Broke My Causal Chain
Listening notes on Gooaye EP709, 28 October 2026: Mong-Kung Hsieh reads out Anthropic's filing — gross margin moving from the low teens to 85%, existing customers spending nine times more a year later, where the eighty-odd billion dollar accounting loss comes from — plus the dilution clause inside the Broadcom lease and four to eight hundred billion dollars of future commitments. Educational notes only, no investment advice, no calls, no price targets; figures are as spoken on air and my reading may be wrong.
Running MiniMax H3 Without a Big GPU: I Turned “Borrow a Colab Card, Give It Back When Done” Into a Public Repo
colab-gpu-runner is a public GitHub repo. One command on your own computer borrows a 96GB G4 GPU from Google Colab, turns a single photo into a short video with sound, upscales it, interpolates it to 48 fps, releases the machine, and pulls the files back through Google Drive with a SHA-256 check on each one. This post covers what it does, who it suits, how to install it, and which card to ask for, then makes the strongest case against it and lands on when it is worth using. A technical learning note, not commercial advice.
What really separates a V60 from a KADOU starburst? Six pour-over questions, answered with a moving model
On October 25, 2026 I put a pour-over station in the blog's lab that moves with its sliders, running on a simplified brewing simulation with five drippers and five pour methods. This post works through six questions: how much the dripper, the pour method and the grind each change, which common claims a manufacturer has actually written down, and where the model is wrong. A technical learning note.
Same Green Beans, One Batch Sour and One Bitter: Seven Questions Answered With a Moving Coffee Roaster Model
On October 22, 2026 I added a 74-part coffee roaster to the blog's lab that moves with the sliders, driven by a simplified roasting simulation. This post works through it as questions: the turning point, first crack, development time ratio, what heat and charge temperature each do, which numbers are common roasting guidance and which are just model output, and where the model goes wrong. A learning note, not advice.
Free and “Zero Retention”? Picking a Model in OpenCode for Sensitive Work Taught Me to Ask Who's Making the Promise
On October 17, 2026, I went looking for a model in OpenCode that could handle sensitive data, actually do the job, and not cost much. The top-scoring free model trains on your prompts, and so does the cheapest first-party API. I settled on a free model whose docs promise zero retention, but the upstream host is never named, so I emailed OpenCode to ask. This post takes apart how much that promise is really worth, with a price-and-policy comparison. A technical learning note, not business advice.
Building a Moving Espresso Machine in a Day: Drawing It Part by Part, and Simulating a Shot With Four Formulas
On October 14, 2026 I replaced the blog's espresso lab with a 110-part machine that moves with the sliders. Here is how it was drawn, how the code checks its own drawing for mistakes, and the four simplified formulas behind the extraction simulation, along with where they go wrong. A learning note, not advice.
Three Shots in One Clip, 24 fps Doubled to 48: An AI Short Film That Took Four Runs
A small experiment log: making the 27-second AI short 'A Little More Every Day' with MiniMax H3 on a Google Colab A100. New this time: cutting three shots inside one clip, pinning storyboard stills to exact frames, and doubling 24 fps to 48 with open-source RIFE. Timings for each step, what broke in each of the four runs, the compute units spent, and whether the dialogue actually came out. The character is an AI creation.
He Bought a Mac Studio and Won't Run Local Models on It: Xiaotian's “Dumplings for a Dab of Vinegar,” and What I Found Timing Seven Days of My Own AI Work
In an October 12, 2026 video, Xiaotian (小天fotos) says he bought the 96 GB Ultra Mac Studio and doesn't plan to run local models on it. When he broke down one After Effects project an AI agent did for him, model output was only 22% of the time; most of the rest was waiting on tools and renders. I broke down seven days of my own AI work and the model's share came to 29%. This post covers his vinegar-and-dumplings idea, lines up six big-memory machines by their official specs, and asks whether it's worth buying a big-memory computer just to run models. A technical learning note, not business advice.
Making AI Short Clips with MiniMax H3 on Colab: Is 2K Worth It?
On October 12, 2026 I ran the MiniMax H3 video model through ComfyUI on a Google Colab Pro A100, generated 3-second clips at 1344×768, and upscaled them to 2K with Real-ESRGAN. Each clip took 206 seconds end to end with a GPU memory peak around 52GB. After comparing both versions, 768 was enough; the story is what decides whether a clip works. Includes the Colab gotchas I hit, the license terms worth reading, and three routes to 2K side by side. A personal learning note, not business advice.
Reshooting an AI Short Film: Testing Three Quality Settings for MiniMax H3 on a Colab A100
A lab note: nobody understood the first cut of our AI short film Daijoubu, so I rewrote the script around four problems, generated a fresh starting photo for every shot, and tested three quality settings on two shots on a Google Colab A100 before shooting all 13 clips. Timings and compute units for each setting, what the full shoot cost, a first run that produced nothing, and how the characters got to say their own lines this time. All characters are AI.
When the Answer Comes Too Fast, the Learning Doesn't Happen: Notes on “How to Keep Learning in the Age of LLMs”
In an October 4, 2026 post, engineer Oğuzhan Olguncu admits that instant AI answers drained his motivation to learn. He lays out four fixes: use AI as a tutor rather than an answer machine, struggle before you look, plan your stages ahead of time, and make progress visible. This post walks through his approach and adds my own take: the question worth asking is which part of the work we hand to AI. A personal learning write-up.
Days of EQ Tweaking, Then One Room Measurement Fixed the Bass: SweetVox V2.0 and an Ordinary Mic
On October 8, 2026, I used an AI assistant to rebuild SweetVox, my homemade audio mixer, into V2.0. I'd spent days nudging the equalizer within ±2 dB. What finally took the sound from good to great was measuring the room with an uncalibrated microphone: 63 Hz went from +9.0 dB to +0.1 dB. Here's the case for and against, eight steps you can follow, and the open-source code. A technical learning share.
From Chat Box to Colleague: What the Four Cloud AI Agents of the Past Month Actually Changed
TechWave EP157 lines up Instinct, Grok Bot, Muse and OpenAI's Dots, covering product positioning, security mechanisms, two business models, and a CPU demand estimate. These are my notes and extended reading — educational industry commentary, not investment advice, and no stock recommendations.
Running Three AI Coding Agents at Once: What Actually Gets Stuck? Orca's Demo vs. My Own Day Running Three Seats on Windows
In an August 21, 2026 video, Joe Maddalone used the open-source tool Orca to run three AI coding agents in parallel, each in its own git worktree. This post digs into one argument: worktrees fix agents overwriting each other, but not quota and not review, so adding seats moves the bottleneck onto you. Includes a comparison of Orca, herdr and Claude Code's built-in worktree flag, plus the snags I hit running three seats on Windows on September 22. Technical learning notes, not business advice.
We Lost the English Textbook CD, So I Built a Reading Machine from a Webcam and an AI
My kid needed the textbook audio to practice English, and the CD was nowhere to be found. I clipped a webcam onto an old laptop and wrote two tiny scripts with an AI: one takes a photo of the page, the other reads it aloud slowly in a natural offline voice. Here is how it works, how it compares with other options, what it can't do, and the full code at the end so you can use it. A personal write-up.
Is a Free AI Gateway Really Free? Free LLM API vs. OmniRoute, Argued Both Ways: It Depends on What You Send
In a September 4, 2026 video, Joe Maddalone shows Free LLM API stitching the free tiers of thirty-plus AI services into one endpoint, so a coding agent picks its own model and costs nothing, and compares it with OmniRoute. This post makes the strongest case for it, then argues the other side by checking each provider's official terms for the hidden price of 'free', and ends with my own experience routing work across several AI services. A personal technical write-up, not commercial advice.
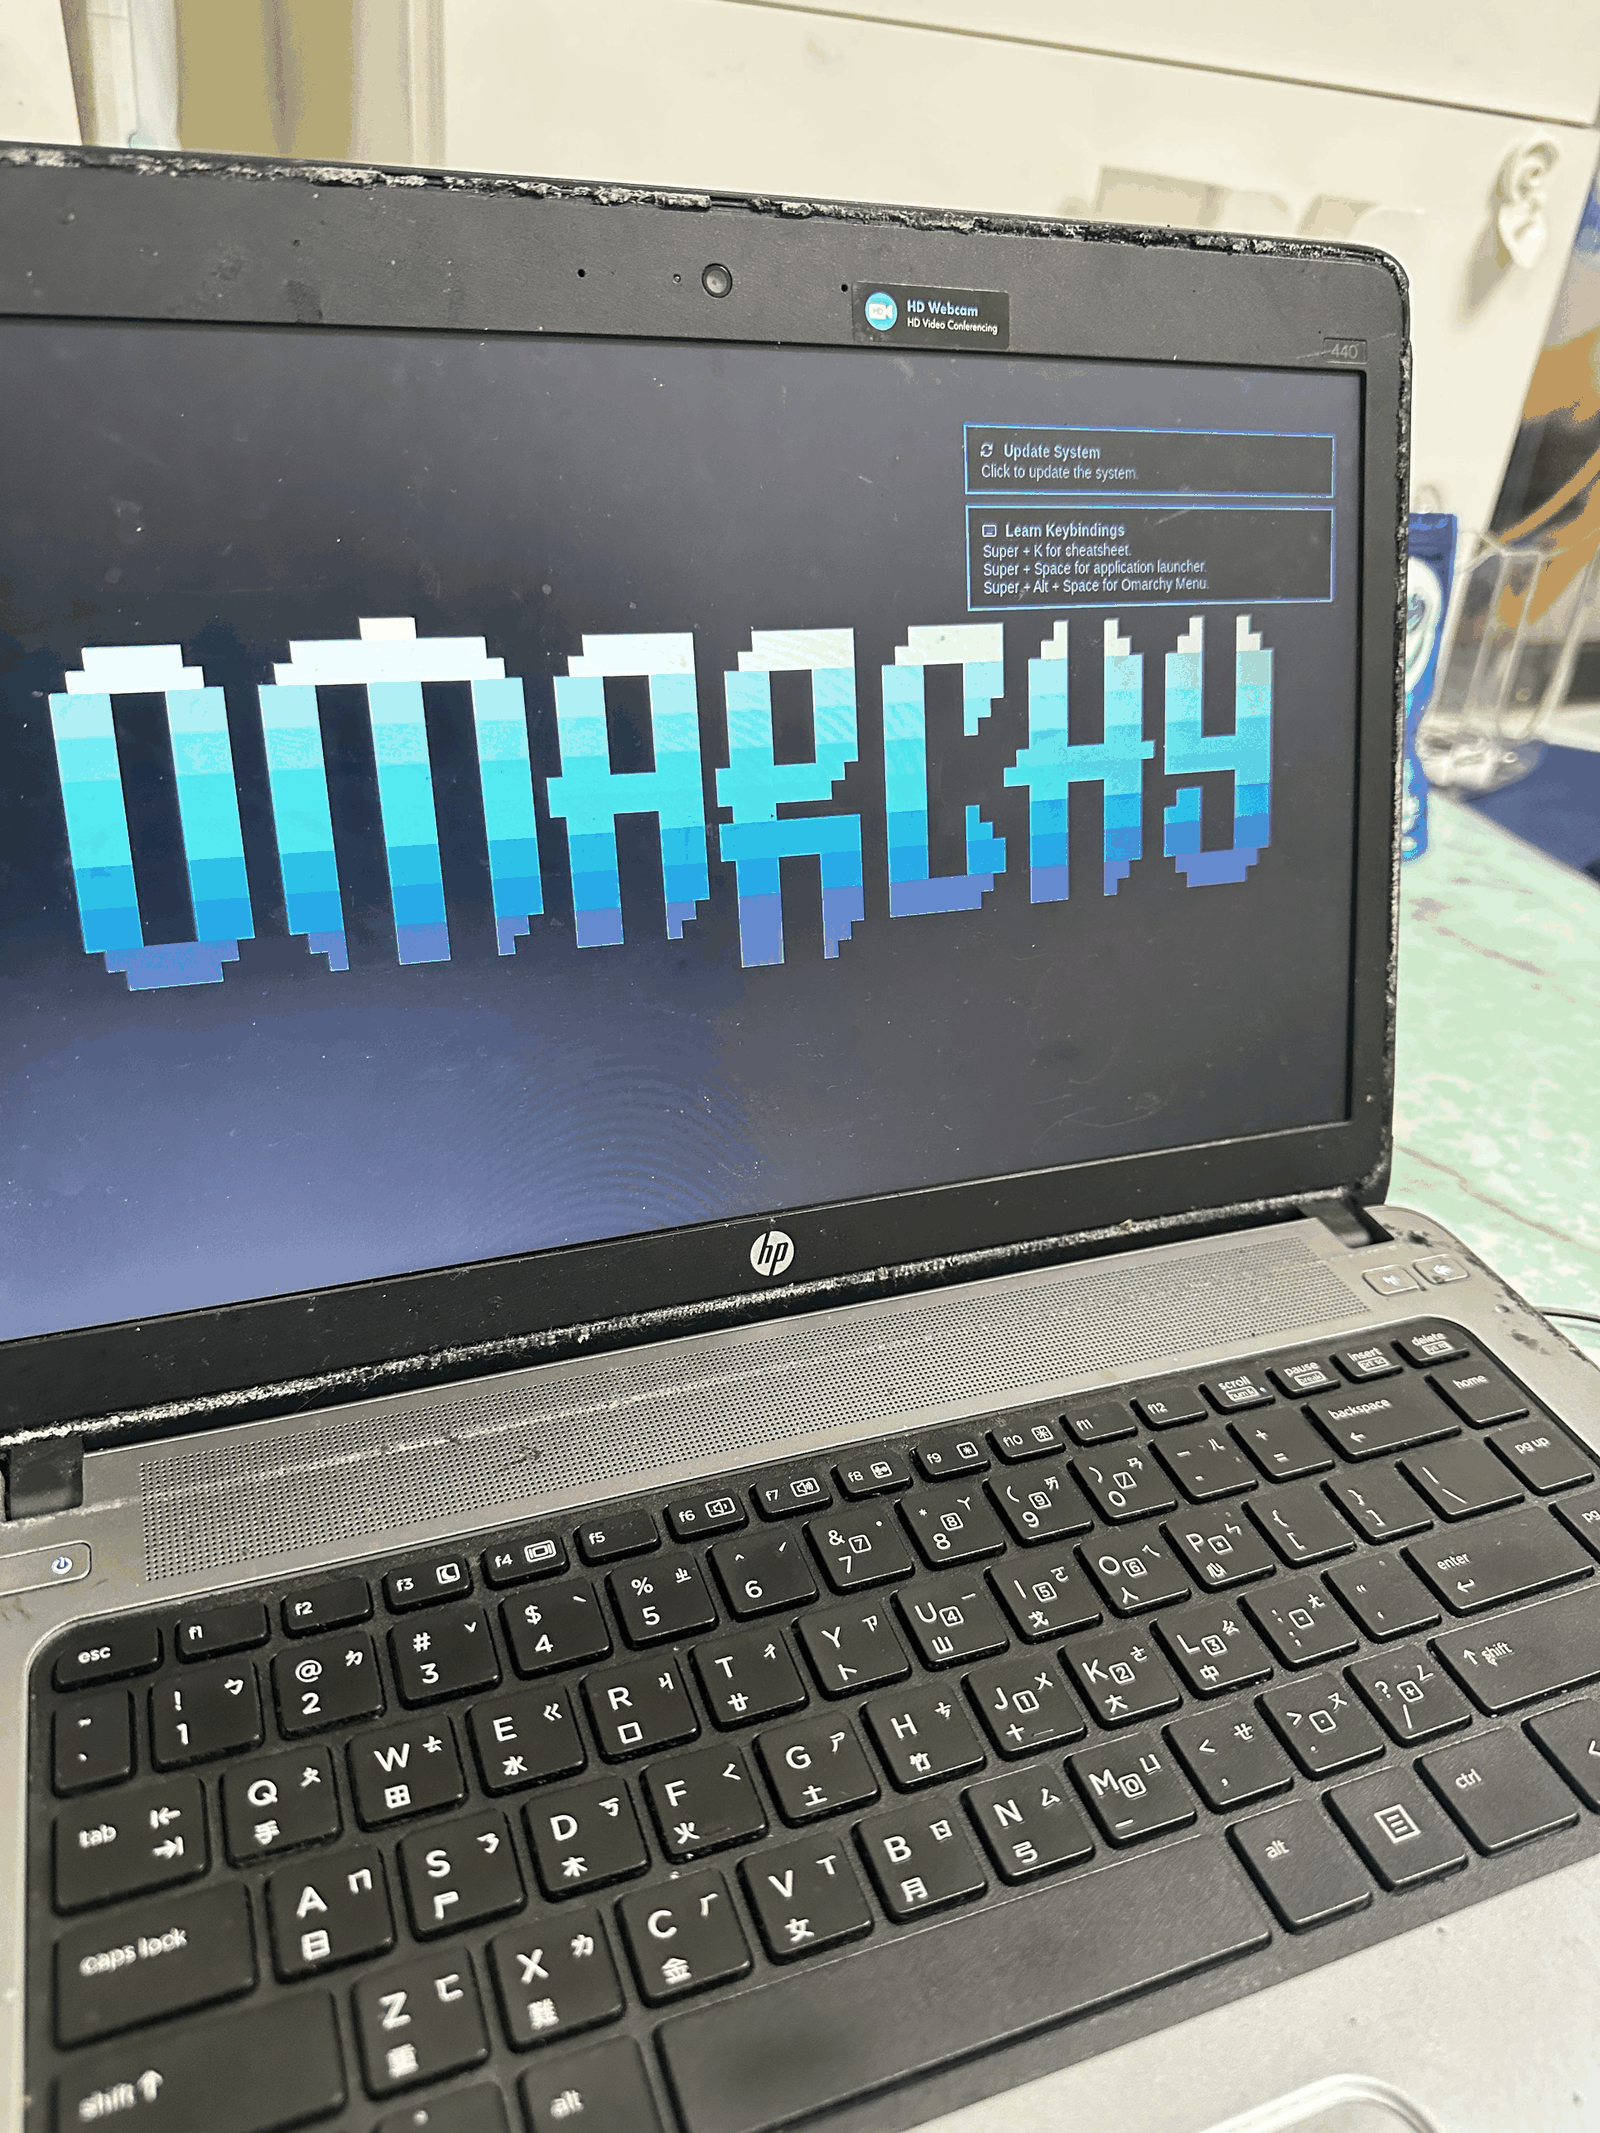
I Let AI Turn My Old Laptop Into a Home AI Server
An old HP laptop still running Windows 7 had been sitting in a drawer. I plugged in an install USB stick, typed a few short commands and entered my own passwords; AI did the rest over SSH from my other computer, installing Arch Linux and Omarchy, full-disk encryption, Tailscale and input methods, while keeping Windows 7 intact. What it did, where it got stuck, what it couldn't do, and the steps if you want to try it. Personal notes.
Is My AI Assistant's Data Safe on DeepSeek? I Read the Privacy Fine Print at OpenCode Go and OpenRouter
In October 2026 I wanted to move my home AI assistant off DeepSeek's official API, mostly for data sensitivity. This is what I found, in order: OpenCode Go costs $10 a month and lists DeepSeek as '0-day retention', but that agreement only runs to October 31; on OpenRouter, 31 providers serve the same DeepSeek V4.1 Flash, 25 of them are on its zero-data-retention list, and DeepSeek's own endpoint is not. Then the math on when a subscription beats pay-as-you-go. Personal notes, not a recommendation for any service.
Renting GPUs on vast, and How It Stacks Up Against RunPod: Booting Up Costs More Than the Rent
Notes from renting cloud GPUs on vast.ai and RunPod in September 2026: an RTX 3090 on vast at $0.22 an hour, 50 images for $0.18; how to choose between the two and where each one bites. A personal write-up, not an endorsement of any service.
A $0 AI App? Walking Through Hugging Face Spaces, Then Finding the Three Conditions Behind “Free”
In a September 11, 2026 video, Joe Maddalone built a background-remover app on Hugging Face Spaces in under ten minutes, called it from his own machine through an API, and paid nothing. This post walks through what he did in order, checks the official docs for the three conditions that make "free" work, and compares it with my own cloud GPU rental numbers: when the free quota is enough and when renting a card is the better deal. A technical learning note, not business advice.
Using AI as My MLA-C01 Tutor: What It Did in Four Weeks, and What It Couldn't
Part two of my notes from passing AWS MLA-C01 on September 26, 2026: having AI check the exam specs, write study notes in Traditional Chinese, quiz me five questions at a time with hints, and turn 271 past questions into Chinese audio, plus the things I still had to do myself. A personal study log.
Passing AWS MLA-C01 in Four Weeks: My Route, and the Deadline I Almost Missed
Notes from passing the AWS Certified Machine Learning Engineer – Associate (MLA-C01) exam on September 26, 2026: the exam specs, the English version's September 28 retirement and how I registered in Simplified Chinese instead, a four-week plan, and how I drilled questions. A personal study log.
Enough Fear to Fill the Trenches, Yet War Still Needs a Decision: Reading Westad's The Coming Storm
Yale historian Odd Arne Westad sets pre-1914 Europe beside today's multipolar world. The passage I keep coming back to: fear and resentment between Great Powers are never in short supply, and what actually pushed the world into war was a handful of concrete decisions made during a crisis. An educational reading note, not investment advice.
You Are Not a Knowledge Worker. You Are a Cognitive Athlete.
Reading Tommy Wood's The Stimulated Mind: why a day chopped into fifty-second fragments costs your brain more than long hours do. Educational and methodological notes; not investment advice.